The Undocumented CSV
The CSV has 40 columns and no documentation. Half the dates are strings, half are timestamps, and someone put commas in the numbers. Typical.
You already know what a DataFrame is. You've used Pandas before. But you keep googling the same things — how to parse mixed date formats on load, why merge() doubled your row count, whether groupby().agg() takes tuples or dictionaries this week. This is that reference. The messy parts, not the introductory ones.
Everything below targets pandas 3.x (the examples were run on pandas 3.1). Two 3.0 changes matter throughout: Copy-on-Write is now the only behaviour, and text columns get a dedicated str dtype by default instead of object. On 2.x most code works the same, but the dtypes you see printed will differ.
Pandas is not something you outgrow for everyday analysis. It is single-machine and in-memory, so it struggles once data no longer fits in RAM. Most analysis datasets fit comfortably.
Loading and Exploring Data
CSV imports are where things go wrong. The file looks fine in Excel, then read_csv() silently reads your price column as strings because row 4,892 has a dollar sign. Or the date column comes in as three different formats because someone copy-pasted from two different sources. The gotchas are always in the loading step, so here's the setup code for a clean DataFrame, then what to run on every new dataset.
import pandas as pd
import numpy as np

# Create a DataFrame from a dictionary
sales = pd.DataFrame({
    "date": pd.to_datetime([
        "2026-01-05", "2026-01-12", "2026-01-19",
        "2026-02-02", "2026-02-09", "2026-02-16",
    ]),
    "product": ["Widget A", "Widget B", "Widget A",
                "Widget C", "Widget B", "Widget A"],
    "region": ["North", "South", "North",
               "East", "South", "East"],
    "units": [150, 230, 180, 95, 310, 205],
    "revenue": [4500.00, 6900.00, 5400.00,
                3800.00, 9300.00, 6150.00],
})

# Quick exploration -- always start here
print(sales.shape)       # (6, 5) -- 6 rows, 5 columns
print(sales.dtypes)      # data types for each column
print(sales.head(3))     # first 3 rows
print(sales.describe())  # summary stats for numeric columns
sales.info()             # prints column names, non-null counts, dtypes (returns None)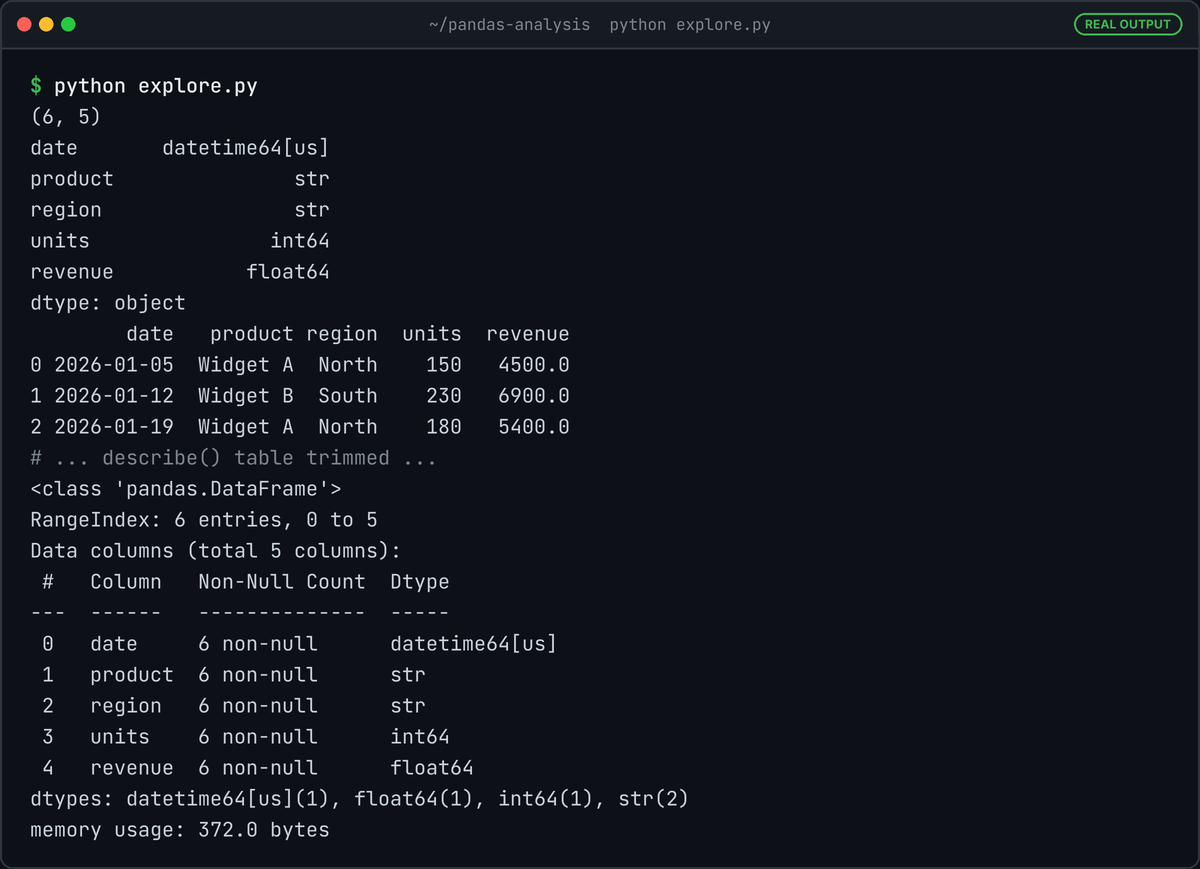
Run those five calls on every new dataset. No exceptions.
dtypes catches the silent killers. A "price" column stored as strings because one row had a dollar sign will ruin a calculation and give you no error message. describe() surfaces outliers: if the max is ten times the mean, investigate. info() shows null counts per column without extra work.
In pandas 3, text columns such as product and region show up as str in dtypes, not object. If a column you expected to be numeric shows str, something in it isn't a number.
For loading from files: pd.read_csv("sales.csv"), pd.read_excel("report.xlsx", sheet_name="Q1"), pd.read_sql("SELECT * FROM orders", connection), pd.read_json("data.json"). The defaults are fine for clean files. Messy CSVs need a few parameters, and setting them at load time beats fixing columns afterwards:
import io

# A messy export: "$" and thousands separators, three date formats
raw = io.StringIO(
    "order_id,order_date,price,units\n"
    '1001,2026-01-05,"$1,250.00","1,200"\n'
    "1002,01/12/2026,$980.50,15\n"
    '1003,"Jan 19, 2026","$2,100.00",240\n'
)

orders = pd.read_csv(
    raw,  # or a path like "orders.csv"
    dtype={"order_id": "int32", "units": "int16"},  # pin types up front
    thousands=",",                  # "1,200" -> 1200 for numeric columns
    parse_dates=["order_date"],
    date_format="mixed",            # infer the format per value
)

# Currency symbols still need cleaning before conversion
orders["price"] = pd.to_numeric(orders["price"].str.replace(r"[$,]", "", regex=True))

print(orders.dtypes)
# order_id               int32
# order_date    datetime64[us]
# price                float64
# units                  int16

# Same idea for a column that is already loaded
dates = pd.Series(["2026-01-05", "01/12/2026", "Jan 19, 2026"])
print(pd.to_datetime(dates, format="mixed").dt.strftime("%Y-%m-%d").tolist())
# ['2026-01-05', '2026-01-12', '2026-01-19']
dtype= stops pandas guessing, thousands= handles separators in numeric columns, and date_format="mixed" parses each date value on its own. Mixed parsing is slower and can misread ambiguous dates like 01/02/2026, so pass an explicit format when the source is consistent. Values with currency symbols stay text until you strip them.
Selecting and Filtering Data
loc selects by label. iloc selects by integer position. The difference that actually bites you: loc includes the stop value, iloc excludes it. Off-by-one bugs everywhere.
But boolean indexing is what you'll use most of the time.
# Single column (returns a Series)
products = sales["product"]

# Multiple columns (returns a DataFrame)
subset = sales[["product", "revenue"]]

# loc: select by label (inclusive on both ends)
row_zero = sales.loc[0]  # first row as a Series
first_three = sales.loc[0:2, "product":"region"]  # rows 0-2, columns product through region

# iloc: select by integer position (exclusive stop)
first_two = sales.iloc[0:2]  # rows at position 0 and 1
top_left = sales.iloc[0:3, 0:2]  # first 3 rows, first 2 columns

# Boolean indexing -- this is where it gets powerful
high_revenue = sales[sales["revenue"] > 5000]
north_sales = sales[sales["region"] == "North"]

# Combining conditions (use & for AND, | for OR, ~ for NOT)
north_high = sales[
    (sales["region"] == "North") & (sales["revenue"] > 5000)
]

# The query() method -- cleaner for complex conditions
result = sales.query("region == 'North' and revenue > 5000")

# isin() for matching against a list of values
target_products = sales[sales["product"].isin(["Widget A", "Widget B"])]

print(high_revenue)
print(north_high)
print(target_products)
The parentheses around each condition when combining with & or |? Required. Without them, Python's operator precedence evaluates & before == and you get a confusing error or the wrong mask.
And query() is underused. It reads more naturally for complex multi-condition filters, avoids repeating sales["column"] everywhere, compiles down to the same boolean indexing under the hood. No performance penalty. A five-line boolean chain becomes a single readable query() call. Use it.
Assign boolean masks to variables. is_north = sales["region"] == "North" makes your code self-documenting and lets you combine masks without duplicating logic.
Grouping and Aggregation
SQL's GROUP BY, but with more room to move. Custom functions, multiple aggregations at once, window operations.
# Total revenue by product
by_product = sales.groupby("product")["revenue"].sum()
print(by_product)
# product
# Widget A    16050.0
# Widget B    16200.0
# Widget C     3800.0

# Multiple aggregations at once with agg()
summary = sales.groupby("region").agg(
    total_units=("units", "sum"),
    avg_revenue=("revenue", "mean"),
    order_count=("revenue", "count"),
    max_order=("revenue", "max"),
)
print(summary)

# Group by multiple columns
multi_group = sales.groupby(["region", "product"]).agg(
    total_revenue=("revenue", "sum"),
    avg_units=("units", "mean"),
).reset_index()
print(multi_group)

# Pivot table -- a more declarative way to group and aggregate
pivot = sales.pivot_table(
    values="revenue",
    index="region",
    columns="product",
    aggfunc="sum",
    fill_value=0,
)
print(pivot)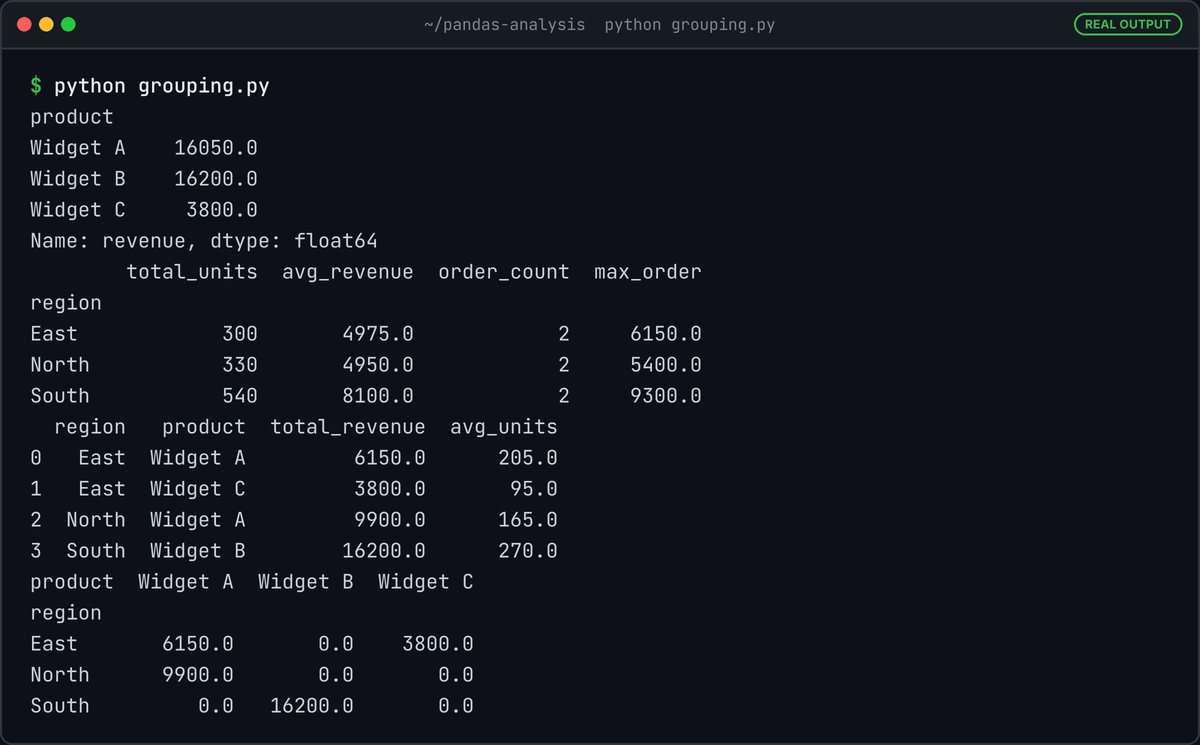
Watch that reset_index() call. Without it, the grouping columns become the index. Annoying. I call reset_index() almost every time.
fill_value=0 in the pivot table replaces the NaN cells that appear when a combination doesn't exist in the data. Not optional if you're doing math on the result.
Merging, Joining and Concatenating
Left join. Same as SQL.
# Product catalog with cost information
products = pd.DataFrame({
    "product": ["Widget A", "Widget B", "Widget C", "Widget D"],
    "category": ["Electronics", "Electronics", "Hardware", "Hardware"],
    "unit_cost": [18.50, 22.00, 31.00, 45.00],
})

# Inner join: only matching rows from both sides
merged = sales.merge(products, on="product", how="inner")

# Left join: keep all rows from the left DataFrame
merged_left = sales.merge(products, on="product", how="left")

# Calculate profit margin after merging
merged["total_cost"] = merged["units"] * merged["unit_cost"]
merged["profit"] = merged["revenue"] - merged["total_cost"]
merged["margin_pct"] = (merged["profit"] / merged["revenue"] * 100).round(1)
print(merged[["product", "revenue", "total_cost", "profit", "margin_pct"]])

# Concatenating DataFrames vertically (stacking rows)
january = sales[sales["date"] < "2026-02-01"]
february = sales[sales["date"] >= "2026-02-01"]
combined = pd.concat([january, february], ignore_index=True)
print(f"Combined: {len(combined)} rows")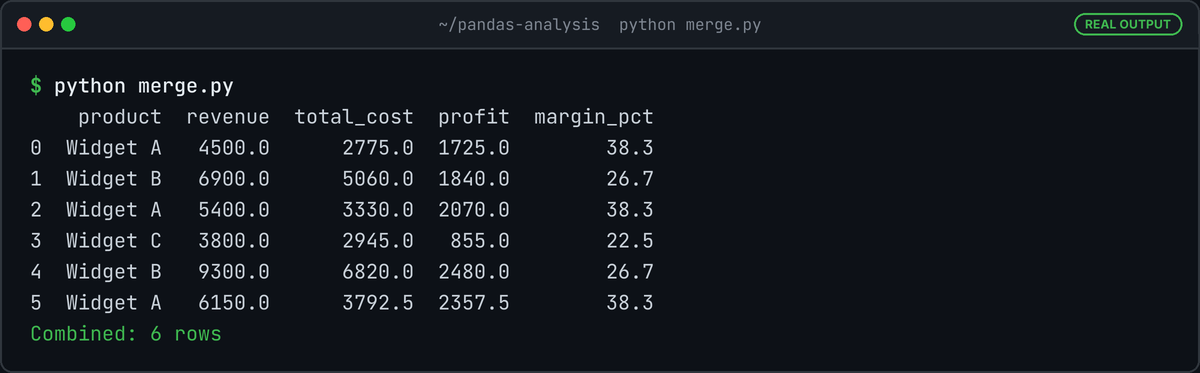
"inner" keeps only matching rows. "left" keeps everything from the left DataFrame and fills NaN where no match exists. "right" does the reverse. "outer" keeps everything. You'll use "left" most of the time because you don't want rows disappearing from your primary dataset.
Duplicate values in join columns produce a cartesian product. Three left rows for "Widget A" times two right rows for "Widget A" equals six output rows. Always check len(merged) after a merge. Bigger than your input? Something is duplicated.
ignore_index=True in concat() resets the index to a clean 0-based sequence. Skip it and you get duplicate index values. Confusing behavior downstream.
Handling Missing Data
Every dataset has holes. The question isn't whether to clean them. It's whether to drop, fill, or leave the gaps and work around them. None is universally right — depends on why the data is missing.
# Create a DataFrame with missing values
messy = pd.DataFrame({
    "name": ["Alice", "Bob", "Charlie", "Diana", "Eve"],
    "age": [28, np.nan, 35, 42, np.nan],
    "salary": [75000, 82000, np.nan, 91000, 68000],
    "department": ["Engineering", "Marketing", None, "Engineering", "Marketing"],
})

# Detect missing values
print(messy.isnull().sum())  # count of NaN per column
print(messy.isnull().any())  # which columns have any NaN

# Strategy 1: Drop rows with any missing values
clean = messy.dropna()  # only 2 rows survive
partial = messy.dropna(subset=["salary"])  # drop only if salary is NaN

# Strategy 2: Fill with a constant
filled = messy.fillna({
    "age": messy["age"].median(),  # median age: 35.0
    "salary": messy["salary"].mean(),  # mean salary: 79000.0
    "department": "Unknown",  # explicit placeholder
})

# Strategy 3: Forward fill (useful for time series)
messy_sorted = messy.sort_values("name")
forward_filled = messy_sorted.ffill()

# Strategy 4: Interpolate numeric columns
messy["age_interp"] = messy["age"].interpolate(method="linear")

print(filled)
print(f"Before: {messy['age'].isnull().sum()} missing")
print(f"After: {filled['age'].isnull().sum()} missing")
Under 5% of a column missing at random? Drop those rows. Larger gaps? Fill with the median (numeric) or mode (categorical). Forward fill for time series where the last known value is a reasonable proxy. Or just leave NaN in place — sum(), mean(), and groupby() all skip NaN by default.
Filling missing values can introduce bias silently, though. Blank salaries filled with the column mean seem fine until you realize high earners are disproportionately likely to leave the field empty. The computed "average" is off by a lot. Ask why the data is missing before deciding how to handle it.
Time Series Analysis
Pandas came out of a quant finance shop. The time series support shows it.
But the first thing that goes wrong: your date column is strings, not datetimes. CSV imports almost always do this. Convert with pd.to_datetime(), set the result as the index, and the full time series toolkit opens up.
# Generate a year of daily sales data
np.random.seed(42)
dates = pd.date_range(start="2025-01-01", end="2025-12-31", freq="D")
daily_sales = pd.DataFrame({
    "date": dates,
    "revenue": np.random.normal(loc=5000, scale=1200, size=len(dates)).clip(min=500),
})
daily_sales = daily_sales.set_index("date")

# Resample to monthly totals
monthly = daily_sales.resample("ME").sum()
print(monthly.head())

# Rolling 7-day average (smooths out daily noise)
daily_sales["rolling_7d"] = daily_sales["revenue"].rolling(window=7).mean()

# Rolling 30-day average for trend detection
daily_sales["rolling_30d"] = daily_sales["revenue"].rolling(window=30).mean()

# Percentage change from previous period
monthly["pct_change"] = monthly["revenue"].pct_change() * 100

# Extract date components for grouping
daily_sales["day_of_week"] = daily_sales.index.day_name()
daily_sales["month"] = daily_sales.index.month
daily_sales["quarter"] = daily_sales.index.quarter

# Average revenue by day of the week
by_weekday = daily_sales.groupby("day_of_week")["revenue"].mean().round(2)
print(by_weekday)

# Shift for comparing to the previous period
monthly["prev_month"] = monthly["revenue"].shift(1)
monthly["diff"] = monthly["revenue"] - monthly["prev_month"]
print(monthly.head())
resample() is groupby for time. "ME" (month end), "W" (weekly), "QE" (quarter end), "h" (hourly). Aggregate with sum(), mean(), whatever.
Rolling windows smooth noisy data. 7-day window removes day-of-week effects. 30-day window reveals monthly trends. The first few values come back NaN because there aren't enough prior points to fill the window. Not a bug.
shift() moves data up or down by a given number of periods. Shift by 1 to get last period's value, by -1 for next period's. Period-over-period deltas, year-over-year comparisons, lag features in ML models. You'll use it constantly once you know it exists.
Performance Tips for Large Datasets
Pandas handles a few gigabytes fine. It slows down fast when used carelessly.
Vectorize Everything
If you're looping with for or iterrows(), you're running Python-level iteration instead of C-level NumPy code. Typically orders of magnitude slower. Time both on your own data; the block below prints the vectorized timing.
import time

# Create a large DataFrame for benchmarking
n = 1_000_000
big_df = pd.DataFrame({
    "price": np.random.uniform(10, 100, n),
    "quantity": np.random.randint(1, 50, n),
    "tax_rate": np.random.choice([0.05, 0.08, 0.10], n),
    "category": np.random.choice(["A", "B", "C", "D"], n),
})

# BAD: Python-level loop over 1M rows (orders of magnitude slower)
# totals = []
# for _, row in big_df.iterrows():
#     totals.append(row["price"] * row["quantity"] * (1 + row["tax_rate"]))
# big_df["total"] = totals

# GOOD: Vectorized -- one call into NumPy for the whole column
start = time.time()
big_df["total"] = big_df["price"] * big_df["quantity"] * (1 + big_df["tax_rate"])
print(f"Vectorized: {time.time() - start:.4f}s")

# GOOD: Use np.where for conditional logic instead of apply()
big_df["discount"] = np.where(
    big_df["total"] > 500,
    big_df["total"] * 0.9,  # 10% discount for orders over $500
    big_df["total"]         # no discount otherwise
)

# GOOD: Use np.select for multiple conditions
conditions = [
    big_df["total"] > 2000,
    big_df["total"] > 500,
    big_df["total"] > 100,
]
labels = ["premium", "standard", "basic"]
big_df["tier"] = np.select(conditions, labels, default="micro")
print(big_df["tier"].value_counts())
Optimize Data Types
Pandas defaults to 64-bit numbers. An integer column holding 0-255 values uses 8 bytes per value when 1 would do. For low-cardinality text, the category dtype stores each distinct string once plus a small integer code per row (one byte per row when there are fewer than 128 categories). Measure rather than guess with memory_usage(deep=True):
rng = np.random.default_rng(0)
cities = ["Austin", "Boston", "Chicago", "Denver", "Houston",
          "Miami", "Phoenix", "Seattle", "Tampa", "Tucson"]
df = pd.DataFrame({
    "city": rng.choice(cities, 1_000_000),     # 10 distinct strings
    "qty": rng.integers(0, 255, 1_000_000),    # int64 by default
})

before = df.memory_usage(deep=True)
df["city"] = df["city"].astype("category")
df["qty"] = pd.to_numeric(df["qty"], downcast="unsigned")  # -> uint8
after = df.memory_usage(deep=True)

print(pd.DataFrame({"before_MB": before / 1e6, "after_MB": after / 1e6}).round(1))
# Example on pandas 3.1 without PyArrow (numbers vary by version/backend):
#        before_MB  after_MB
# Index        0.0       0.0
# city        55.2       1.0
# qty          8.0       1.0
The "before" figure for strings depends on the backend: with PyArrow installed, the default str dtype is already more compact than Python objects, so the gain from category is smaller.
Read in Chunks
Files too large for memory? The chunksize parameter in read_csv() returns an iterator of DataFrames. Aggregate each chunk, then combine the partial results:
import io

csv_text = "region,revenue\n" + "North,100\nSouth,250\nNorth,75\n" * 1000
totals = None
for chunk in pd.read_csv(io.StringIO(csv_text), chunksize=500):  # or a file path
    part = chunk.groupby("region")["revenue"].sum()
    totals = part if totals is None else totals.add(part, fill_value=0)

print(totals)
# region
# North    175000
# South    250000
# Name: revenue, dtype: int64
This works for aggregations that combine cleanly (sums, counts, min/max). Medians and other order statistics need a different approach.
Or just stop using Pandas for that workload. Polars and DuckDB handle larger-than-memory data natively. For data that doesn't fit in memory, they are often simpler than stacking up pandas workarounds like chunking and downcasting.
Avoid Chained Assignment
pandas 3.0 made Copy-on-Write the only mode. Every indexing result behaves as a copy, so the old copy-versus-view ambiguity is gone and SettingWithCopyWarning no longer exists. The flip side: chained assignment such as df["a"][mask] = value now never modifies df. pandas emits a ChainedAssignmentError warning, but the data stays as it was.
df = pd.DataFrame({"a": [1, 2, 3], "b": [10, 20, 30]})

# Chained assignment: two indexing steps, the second writes to a temporary copy
df["a"][df["b"] > 15] = 0      # pandas 3: ChainedAssignmentError warning, df unchanged
print(df["a"].tolist())        # [1, 2, 3]

# One indexing step with .loc does what you meant
df.loc[df["b"] > 15, "a"] = 0
print(df["a"].tolist())        # [1, 0, 0]

# Subsets behave like copies: changing one never changes the parent
subset = df[df["b"] > 15]
subset["a"] = 99               # no SettingWithCopyWarning, no .copy() needed
print(df["a"].tolist())        # [1, 0, 0]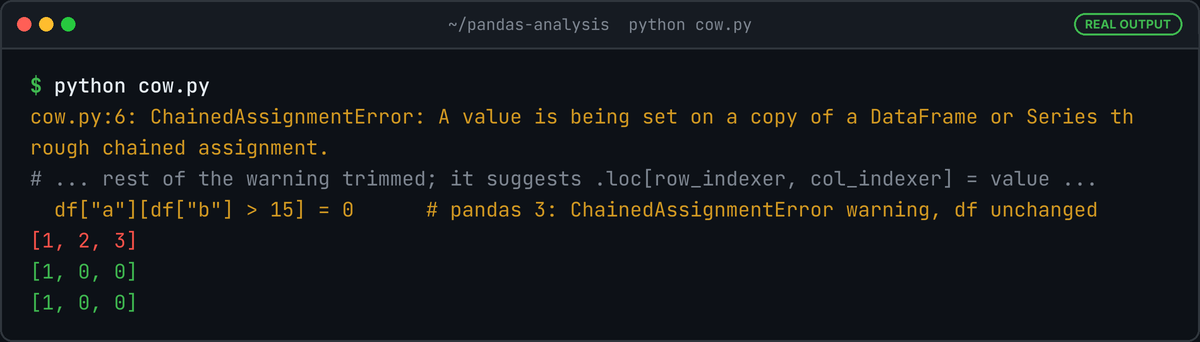
Rule of thumb: write with a single .loc[row_selector, column] call. Defensive .copy() calls added only to silence the old warning can be removed. Copy-on-Write also lets pandas delay copies until something is actually modified.
Where to Go From Here
Pandas covers most analysis that fits in memory: loading, cleaning, reshaping and summarising. Clean types at load time, write with .loc, vectorize instead of looping, and check row counts after every merge. When data outgrows a single machine's memory, or a query engine would do the job better, reach for Polars, DuckDB or a real database instead of piling on workarounds.


